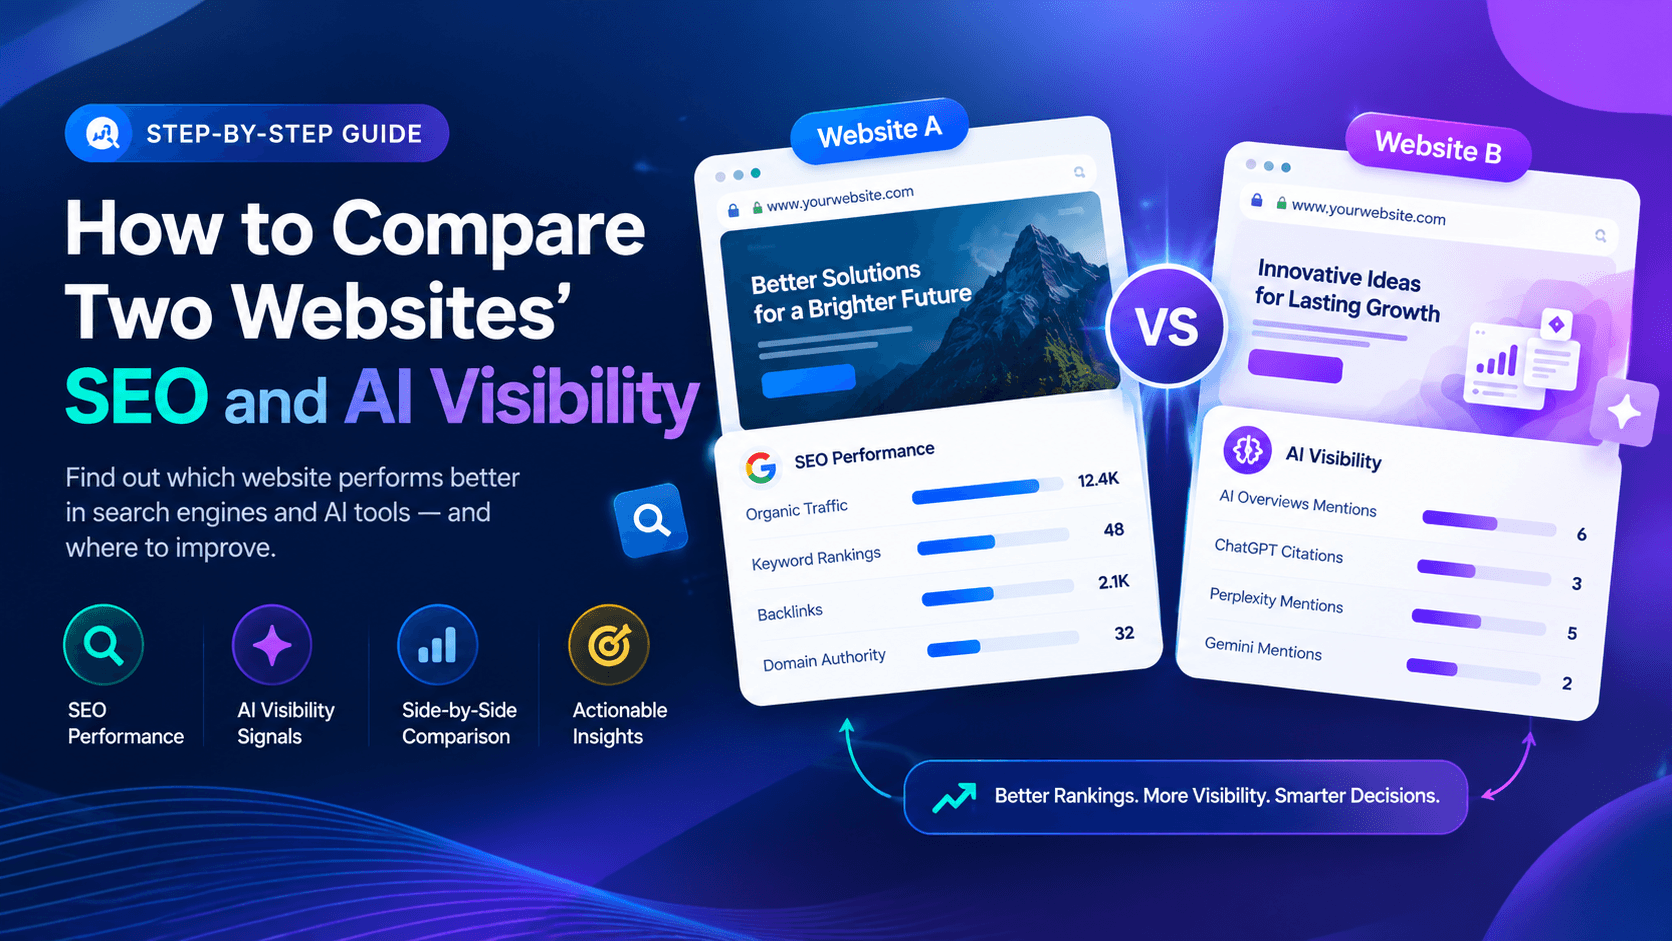

ChatGPT, Perplexity, and Gemini cite the page that answers the question in the first two paragraphs, with a clear heading, a source they are allowed to crawl, and a fact they can quote without guessing. If your site is missing from those answers, the usual cause is not "the model dislikes your brand." The crawler never saw a page it could lift a sentence from.
That is the traffic problem in 2026. People still search, but a growing share of those searches end inside an answer box. You do not lose the ranking you can see in Google. You lose the citation you never earned.
What an answer engine actually needs
An answer engine does three things before it mentions you:
- It fetches a URL its crawler is allowed to read.
- It finds a passage that directly answers the query.
- It checks that the passage is specific enough to quote: a number, a definition, a step, or a comparison.
A homepage that says "we help businesses grow" fails all three. A guide that opens with the definition, then a table, then the steps, gets retrieved.
Direct answer: Generative engine optimization (GEO) is the work of making pages extractable. You write the answer first, allow the crawlers, and give the model a sentence it can repeat without rewriting your whole site.
The five blocks that get a page cited
| Block | What to put on the page | Why models use it |
|---|---|---|
| Answer first | The definition in the opening 80 words | It becomes the quotable span |
| Question headings | The exact query as an H2 | Retrieval matches the heading |
| One comparison table | Options, costs, or criteria | Tables survive summarization |
| Named proof | A metric, a date, a method | Vague claims get dropped |
| Crawl permission | llms.txt plus a robots rule that allows GPTBot, PerplexityBot, and Google-Extended | A blocked URL cannot be cited |
If any row is missing, fix that row before you publish another post. More pages do not help if every page is written the same vague way.
A real failure we see on scans
A services company ranks on page one for "website audit tool" and still never appears in Perplexity. The scan shows three separate problems:
robots.txtdisallows/blogfor every user agent, so the articles that would have been cited are invisible.- There is no
/llms.txttelling assistants which URLs are the canonical explanations. - The top article buries the answer under a 200-word brand story. The model quotes a competitor who defined the term in sentence one.
None of that is a content-volume problem. It is an extraction problem. Run the free scan and read the GEO section before you rewrite the whole site. The same checks are covered in how Google AI Overviews cut your clicks.
What to publish this week
Write one page per money query. Use this shape:
- State the answer in the first paragraph. Include the term people type.
- Add an H2 that repeats the question.
- Add one table or a numbered fix list.
- Link to the next page on your own site. Orphan pages are rarely retrieved.
- Allow the crawlers, then request a recrawl by updating the sitemap
lastmod.
Internal links matter here as much as they do in classic SEO. This article points at the scanner and the INP guide because a cited page should hand the reader (and the model) a second URL on the same domain.
What not to do
- Do not stuff "ChatGPT SEO" into headings that do not answer anything.
- Do not block AI crawlers and then wonder why you are not cited.
- Do not hide the only useful paragraph behind a login. Models cannot quote what they cannot fetch.
If you want the full issue list instead of a summary, the scanner breaks robots rules, missing answer blocks, and slow templates into a checklist your developer can ship. Questions about a specific site go through contact.